
Coffin, meet nail.
Posted: November 15, 2026 Filed under: Education, Opinion | Tags: education, higher education, learning, learning styles, teaching, teaching approaches Leave a comment
An interesting article just showed up on APA PsycNet from the Journal of Educational Psychology, entitled “Debunking the learning styles neuromyth: No effects of learning styles on recognition accuracy in primary education students.” The authors, Papadatou-Pastou, Touloumakos, & Theotokatou, use a sample of 194 primary school students to further refute the notion that underpins the folk pedagogy (neuromyth) of learning styles, that matching instruction to a preferred modality improves learning. The study did show that audiovisual presentation outperformed single-modality instruction for all groups and students’ self-reported preferences didn’t reflect reality.
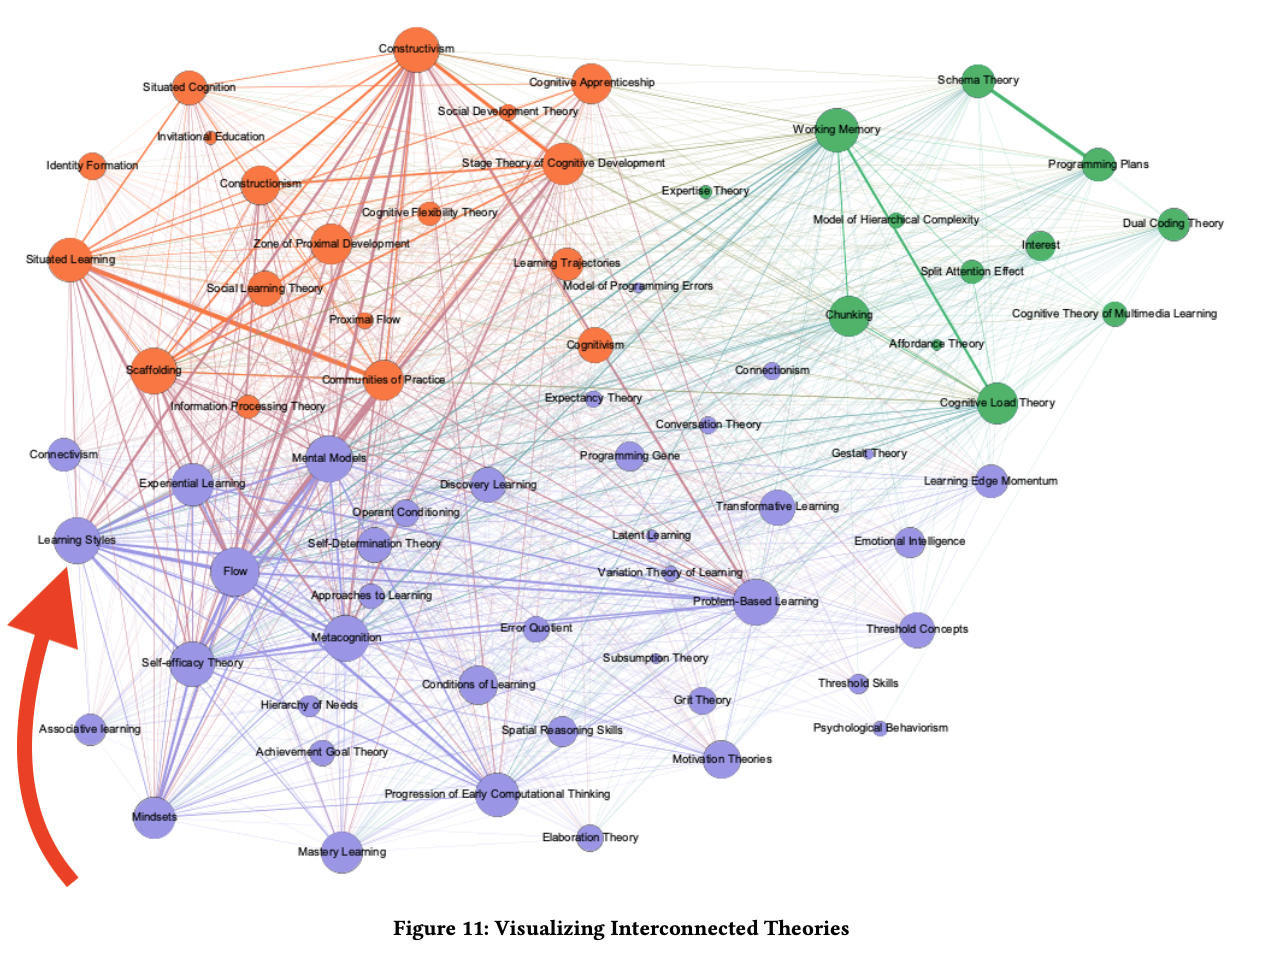
Learning styles have long been a difficult topic in educational research as so many people believe that they are real (For example: someone is a visual learner, someone else is a kinaesthetic learner) yet we have never had strong empirical evidence to justify this belief. What appears to be worse is that someone who does try to match instruction to a student’s perceived style of learning may, from this study and others, be doing them a disservice because they’re ignoring the multimodal approach that seems to work for the vast majority. To give you an idea of how widespread learning styles are, a paper we wrote back in 2017, “A Periodic Table of Computing Education Learning Theories“, looked across the corpus for all uses of learning theories returned a total of 45,210 hits across the ACM DL, 15,557 in CS Ed venues, and, of these, learning styles represented 2,219/1,390 hits respectively – an enormous presence for a theory with no empirical foundation. The diagram below (Figure 11 from the previous paper) shows the relative scale and connectivity of Learning Styles, marked on the lower left side with a very large arrow.
The CS Education community has reduced its use of the term over time, driven by the lack of supporting evidence, but it’s fascinating to see a solidly constructed study that tests key aspects of the learning styles hypothesis and finds it wanting. Now, this is not to say that you can’t, and shouldn’t, personalise learning in other ways, especially in the use of allegories and context to reduce obstacles but there still is no support for the idea that there are groups of students who are genuinely uni-modular in a way that has a measurable impact of their ability to learn.
I think of learning styles as a tombstone area; we have no evidence that it works so we should bury it unless we get enough solid evidence to dig it up. As it stands, it’s not something we should continue to use in educational delivery and pedagogical design. I’m not saying that we will never find evidence to support it but every experiment that comes back with a “no” just adds more weight to the idea that we should leave it behind.
From read only, to read/write, to write only, to … ?
Posted: November 15, 2026 Filed under: Education, Opinion | Tags: AI, artificial intelligence, chatgpt, education, educational problem, reflection, technology, thinking, writing Leave a comment
Now this is long, if you want the 5c version, software developers using Generative AI are starting to generate large amounts of automated text that takes a long time to read, which means that the people checking their software are using GenAI to summarise it and accept the changes. This means that the human role in software oversight is potentially reducing, and quickly. Now to the long version.
The long-winded intro
The interactivity of networked communication has been an amazing development in human information transfer. Books, which are great, are large, physical objects, where you can read what I wrote but you can’t (easily) respond to me in a way that other people can see your thoughts on my writing. It was slow to write books with ink and pen and even the advent of the typewriter and word processor has only sped up the creative act of producing the text of a book by around a factor of five. Printing a book has got much faster, certainly, and electronic distribution of the written word has made it almost instantaneous from decision to print to “here is the book”, but it still takes time to write a book. If you assume a book length of 80,000 words, it’s about 133 hours of handwriting to to produce those words, or about 27 hours if you’re not a bad typist and don’t stop to eat, sleep, or breathe. This doesn’t allow any time for thinking, plotting, drawing complex diagrams, or edits, but it’s a way to think about how much human time and effort is required to write a book. I once wrote 50,000 words in just over 20 hours for a charity writeathon and I can tell you now that I could barely talk when it was done. Many authors write somewhere around 1,000 words a day, which would mean you’re waiting close to three months for a book. Actual writing, with content and thinking, takes time.
On the receiving end, humans read around 260 words per minute, far faster than people type and anyone handwrites, with that 80,000 word book taking a little over 5 hours to read (you have a comfortable chair). You don’t have to write a response to the book, you just read it, think about it, and you’re done. Of course, we’ve been sending each other much shorter messages than books for ages – messages sent by messenger, courier, or postal service to exchange business information and personal thoughts, have been around for thousands of years. But both of these have one thing in common in that the written entity is given to us and we never really modify it. A letter exchange has input from both sides but through the exchange of individual read only elements, with the time between letters determined by how long the first took to write, that one took to send, the time for the receiver to read and craft a response, and then choose to send it again. Individual letters could be collected, physically, or by being printed into a volume, but they remained a set of independent read-only messages.
One of the first new communication models to emerge after we started connecting computers together was simple messaging, then e-mail and discussion boards, and it’s in discussion boards that we started to see a read/write aspect to a conversation really emerge. Discussion boards provided persistent containers for the organisation of messages and responses to those messages (and responses to responses…), suddenly changing an information exchange between multiple people into something that could be changed by both parties. The ability to edit and change shared pages took this even further – Wikipedia, for example, is something many people read, but what you read is the product of hundreds or thousands of people in an ongoing conversation as they change any or all parts of the information on the page. LiveJournal, a long form social media site from the past, was often joked about as being “write only”, because users would produce long articles about things that mattered to them, shared onto a feed where others could read (and comment), but they ignored any comments that came their way as they weren’t interested in dialogue but broadcast. Books are broadcast. A set of letters can be a conversation, if stored correctly. A discussion board or social media site provides mechanisms to support a useful dialogue, with varying levels of editing older information, although sometimes it’s just people shouting at clouds.
Oh, Bruv New World
Under all of this is a simple assumption, that all the words were created by someone, with an intention of being read by someone else. This assumption broke a few years ago and this breakage is having some serious ramifications across a range of spheres.
The advent of generative AI means that novel length words can be generated in the blink of an eye by a short prompt, channeling the stolen work of millions of people to pump out a notional novel in seconds. It no longer takes 27 hours of typing, and goodness knows how many days of thinking, to produce a novel. Of course, another aspect of generative AI is using it to summarise works or reports for you, which means that it no longer requires 5 hours to read a novel – you can get a summary in seconds. This, of course, would have an immediate effect on fiction publishing, especially if people are happy to read AI generated work. If someone is still reading manually, there are only so many books that they can read in a year – which means the more AI generated ones they read, the fewer human ones they can read.
I don’t know quite what to call a model where an AI writes the book, and a human claims authorship, and then another person uses AI to summarise the book, and says that they’ve read it. It reminds me of the human/robot discussions of the late science fiction writer Philip K. Dick, who wrote about the blurred lines between creatures that say that they’re one thing but may be another. For me, and no doubt many will disagree, authorship requires both the creative intent and the work to bring it to fruition – ideas are cheap, effort is what brings them to the world. Someone writing large books using a small AI prompt is not, in my mind, an author. But I don’t have another word for it quite yet. I do feel that someone who is only reading short summaries of books has not actually read the book – they may have the gist, or even a good idea of the ending, but they do not have the knowledge of the way that the book was written or any idea of the many themes and nuances that were used in the book. Sure, they’re still reading but have they read this book? Sorry, I don’t think so.
Is this really new?
The generative contribution to verbosity is new. From the moment we made it easier for people to add volume to their text through cut and paste, whether physical or electronic, texts have been getting bigger. When legal judgments went from hand written to computerised, pages and pages of former cases could be added at no effort to the crafting judge. While this notionally added important information, this low effort inclusion of additional information put a greater burden on anyone seeking to read the judgment later. Before generative AI, this burden was shouldered by junior lawyers and clerks, as summarising the case required someone human to do the work. After generative AI… it has become far easier to generate a large volume at the start and then summarise it to (notionally) salient points without all the human labour. I say notionally as, of course, LLMs are prone to error and hallucination, and any generation or summary could be wrong. If a human is doing the summary, then they may spot a generative error – may.
At its core, we have to look at the role of the human in here. There is a finite limit to the speed with which humans can read and write, which limits the speed of producing and analysing written texts. No argument. But speeding this up, using non-human means, should probably not be at the loss of accuracy, quality, and usefulness of the information in question. The slowness of humans is a limit, not a benefit, but the price of using human intellect, training, and expertise is that they have a speed limit. We probably don’t want our legal judgments to devolve to “hey, Siri, give me 10 pages of why he’s guilty”, and “yo, read these 10 pages, summarise to one sentence and three bullet points for case for appeal.” The “didn’t bother to write it”/”not going to bother to read it” model has got some pretty obvious pitfalls in it, even in the simplest of cases.
Real World Impact
The didn’t write/didn’t read model is one we can look at in fiction as a curiosity, and get a slightly worrying feeling about it’s use in law, but there’s another place where DW/DR can actually cause trouble and that’s in the area of software development. For those who don’t know about large scale software engineering, it’s often built on a repository model, where the pieces of code are stored in a central repository that tracks versions, allows integrated testing, developers to exchange comments and raise issues, and, ultimately, makes large and intricate code bases easier to look after. A number of these are built on software called git, which is a distributed version control system, and developers can take a piece of code, change it, test it, and then, when it’s accepted, merge it back into the main software so that their changes are used in the current production version.
The online platform GitHub uses Git with a large amount of project management wrapping to let people from all over the world work on code in a controlled and systematic way. Ideally, for a given section of code, any changes are only being made by one person, all changes are properly tested, and then these changes are presented back to a moderator of some sort to check so that one person changes and one other person checks. The developer works on a branch pf the main software, makes changes, is happy that it works, then uploads it back to the server. Then they issue a pull request, where they compare what they’ve done to the main branch, add a description of what they’ve done, tag any issues they believed they’ve fixed, and ask someone (or nominate) someone to review their new code. This code is then run through automated tests and continuous integration systems to make sure it doesn’t break immediately, then what should happen is that a human reads through the PR, checks the code, writes any comments, and, once approved, the code is then merged to the main branch. This code is now part of the main build.
But what has started happening with the use of Generative AI is that the effort required to write long and copious notes on software changes is diminishing. If GenAI is generating your PR, it can lead to longer descriptions and longer issue statements. Now this wouldn’t be a problem by itself, except that the frequency of PRs are increasing as people use GenAI to write code to solve issues. Now the humans doing the review have got both more text to read in an individual PR AND more PRs. So what are they doing? There’s clear evidence that more people are using GenAI to analyse the code in the PRs and get a tick of approval. In some cases, the GenAI is authorised to do the merge if the PR passes muster.
What this means is that what should have been a benefit, increased code output and increased description, has now started to push people out of the checking loop. Code is being generated so fast, much faster than humans could, that it’s exceeding what the reviewers can handle, which means that they’re having to use Generative AI to keep up. And that means that true human oversight of code changes is reducing. And, remember, LLMs sometimes make things up, sometimes are wrong, and are often random in unpredictable ways – all code generated by them needs oversight, just as human written code does.
We’ve already seen an unpleasant dehumanising of lower quality educational systems where overworked teachers use GenAI to generate worksheets that performance-driven students use GenAI to complete and which are then marked by GenAI because the teachers don’t have time. A scenario where not only do we not have confidence that anyone is learning anything, but we literally have no way of knowing because all of it is being done by AI. This is potentially damaging and dangerous to students if left unchecked.
Now imagine a software future where Claude writes the code, ChatGPT writes the PR, Copilot does the checks, ChatGPT writes some comments, Claude notionally responds and then merges this to the main branch. Let’s assume that each of these is 95% accurate, the chances of this code and all of its documentation being correct is around 77%. Now humans are certainly not perfect but they are, in this setting at least, also not random in their solution seeking. Programmers work on a design, where a lot of the work in the software is done before any code gets written, often using tools such as very specific types of diagram, relational modelling, and markup languages, to ensure that the code, when written, is more likely to be accurate. Also, skilled software developers can be very good at spotting bugs in code and there is an intentional mental discipline and a set of semantics that underpin the writing of code – humans do not write code randomly and we know that they can have a far more detailed mental model of a system than any current LLM can manage.
After having six Severity 1 incidents in a week, Amazon backpedalled rapidly on their unsupervised deployment of GenAI-assisted code and now senior engineers have to sign off on everything. Suddenly, the Sev 1 rate dropped. Hmm.
Every time that I read about how much faster we can write code with GenAI, I am reminded of the Simpsons episode where Bart is trying to demonstrate his intelligence by playing chess against three people simultaneously (“The PTA Disbands!”, Season 6, Episode 21). Immediately after someone saying “Hey, that boy is playing three games at once!” he is checkmated on all boards, as he may be playing three people but he’s not playing well. GitHub has fallen over many times for capacity in the last two years as the change rate has exploded with GenAI code changes being pushed, but we’ve also seen a sharp spike in code revisions, where merged changes have had to be removed because they didn’t work and none of the tools used picked that up.
There are ways of using these tools to reduce some grindlike aspects of programming but they are nowhere near accurate enough to operate without some form of human oversight, and this means that humans have to be able to read and digest all of the associated documentation and code changes. The “Didn’t write/didn’t read” model is hard to justify in any setting but it’s extremely dangerous in the area of programming, as it is not mature enough to produce working systems at the same level of reliability as before, and it robs everyone involved of the opportunity to develop and maintain their skills.
I fear that we are just playing bad chess on millions of boards and that there is a looming wall of checkmates.
Lazy Matching – A Personal Example (#Kolicalling 2026)
Posted: November 11, 2026 Filed under: Education, Opinion | Tags: education, teaching approaches, thinking, writing, technology, AI, artificial intelligence, kolicalling 2 CommentsI hesitate to write this because it might make a bery mildly irksome situation worse but it’s a useful example.
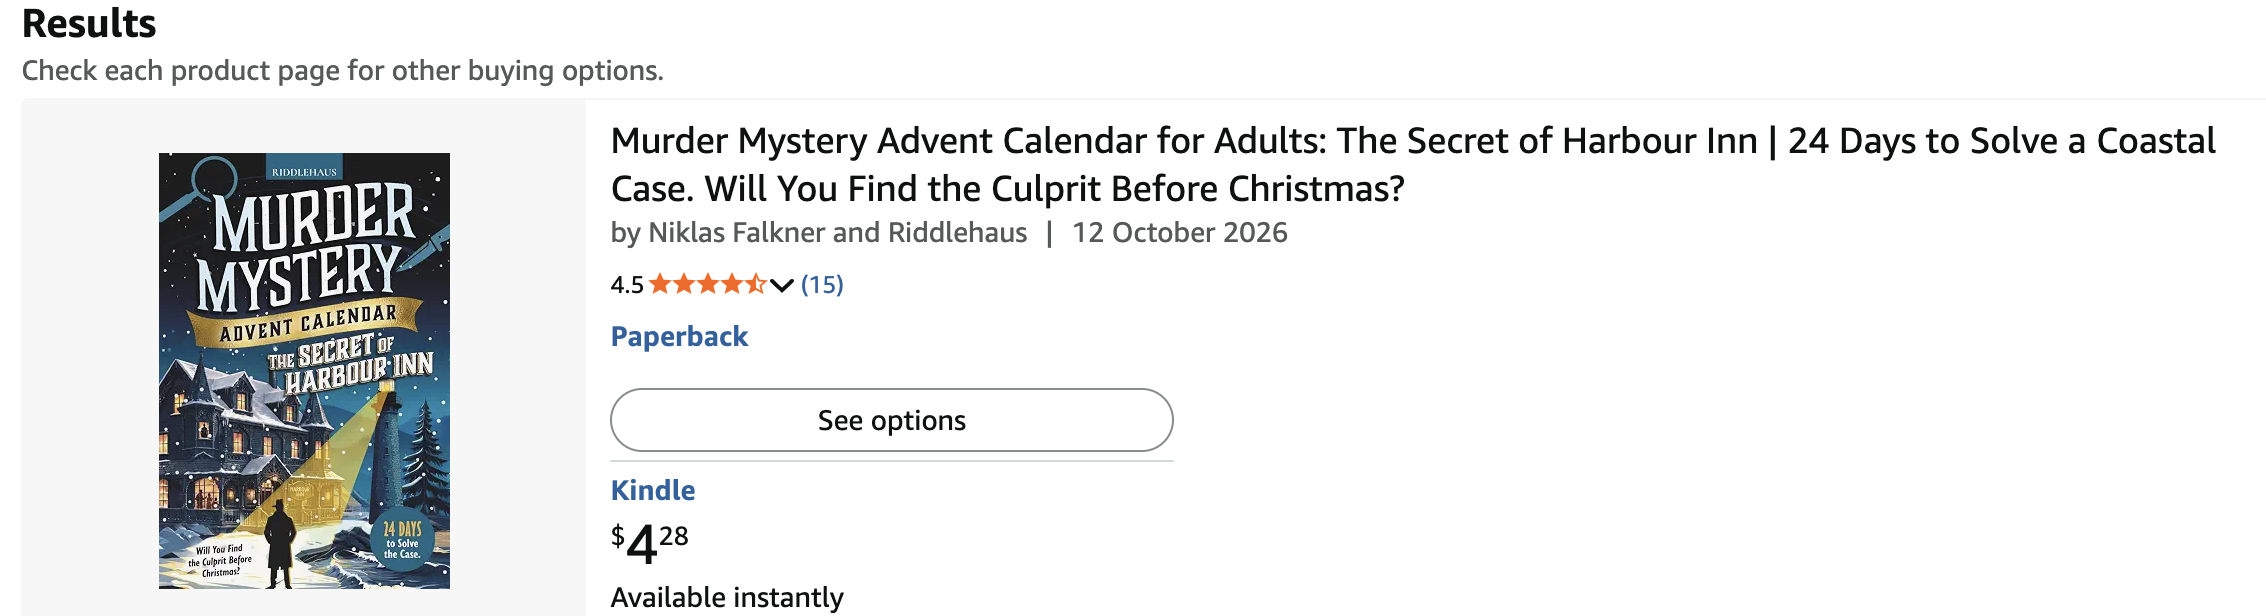
Christmas is coming, which means that Advent Calendars and associated items are showing up everywhere. It turns out that there is a family of murder mystery advent calendars written by someone with a very similar name to mine. I won’t put it in text, for reasons that will become apparent, but you can read it above.
I have commented elsewhere about one of the problems with using generative AI instead of a search engine is that you are generating a result which will resemble the answer to your query, rather than directly using a search function to explore a defined search space. One of the results of this is can be that the GenAI will generate something in response to your query rather than telling you that there is no answer to return. This is far more likely when there is a near match in information that it has already assimilated.
Let’s talk about an example I just saw at a conference, Koli Calling 2026, held in Koli, Finland. I saw a great demonstration at the conference of a Generative Story Telling machine that exposed how the story telling was influenced by the underling stochastic nature of the generator AND the existing data that was used to train it. You can find the abstract here: “Three Lenses for Exploring Training Data and Language Model Outputs in K–12 AI Literacy“. The Little Language Machine uses a browser based tool to train and deploy small language models, but can show you what the options were in the output, allow you to take alternative paths, and make it clear how much stochastic play there really is in the outputs. This makes it easier for learners to use evidence to reason about the relationship between what goes into and what comes out of a generative model.
The specific example started with “Once upon a time, there was a ” and then we got a story about a girl called “Jane” (I think). When you selected “Jane” in the text, you saw all the other names it could have been. “Jane” had a likelihood of 5% and “Lucy” was 15%, which clearly showed that, despite Lucy being more likely, a perfectly valid outcome was Jane. Then the demonstrator typed in something like “Once upon a time, there was a girl called Zendaya” and this generated a story that was fine for the first sentence and then the name suddenly became “Zip” and, as the story went on, Zip’s gender pronoun shifted between male and female. Why? Because the story training had never included the name Zendaya and the machine was matching to what it had been trained on, which included names that were partially matched, with associated gender, but somewhat randomly.
Now, of course, you can all start jumping up and down about how this wouldn’t work in a very large model, or agentic wrappers would fix it, but the point remains that generative solutions rely upon their training data and will often not return a “not found”, instead they stumble around with as close a match as they can manage but their stochastic nature means that even that close-ish match will change from time to time.
Hence, the author of the books above is close enough to me to cause a series of queries from publishers and conferences and promoters all seeking to speak to that author, who does not appear to be as visible on the Internet as I am and so I get the hits – all of which, I hasten to add, smell of AI generated text.
A human would probably look at our names and wonder why I would alter my name in that exact way, given that at no stage have I ever used that as an abbreviation but the LLMs don’t wonder, they just provide something approximating an answer. (I also started getting an abbreviation of my first name I don’t use about two years ago, probably being autocorrect or gen-influenced, and I always reply with my name in my sig block but it doesn’t seem to shift it.)
Approximate matching is not a new thing. Years ago, well before the dawn of computing, we had Soundex Codes for indexing names, where a code is generated from a phonetic English interpretation of a name. The code comes from the leading letter of the name, followed by three numbers that indicate other consonants in the words. The numbers used stand for consonants that sound “similar” in English, so we use the numeral “1” for B, F, P, and V, for example. This would lead to Robert and Rupert both having the code R163. Soundex was valuable back when name spelling was highly inconsistent, search costs were high, computing power was non-existent, and we wanted to be able to find things that should be grouped together.
Soundex was used to make indexing more efficient, not to falsely tell us that Robert and Rupert were the same name. Yes, under Soundex, my full name and the name on the text have the same code, N242, but that should just put us in a convenient index to say “we seem to be phonetically similar”, not that we are the same person. There’s a point where Robert and Rupert are not the same person, and that point is reached before you write to Robert to ask about Rupert’s books.
I really liked the example at Koli because I imagine many people are seeing this happen without realising what is going on and what it means in terms of how things are currently working. The more we understand that a number of results we see are synthetic close matches, rather than true answers, the more cautious we need to be about the information that is returned to us as fact.
Of course, now I have to start writing my own advent calendar murder mysteries to take advantage of this new career direction…
Lifting Weights: An Analogy for Learning That I Like
Posted: October 27, 2026 Filed under: Education, Opinion | Tags: education, generative AI, higher education, teaching approaches, thinking 3 Comments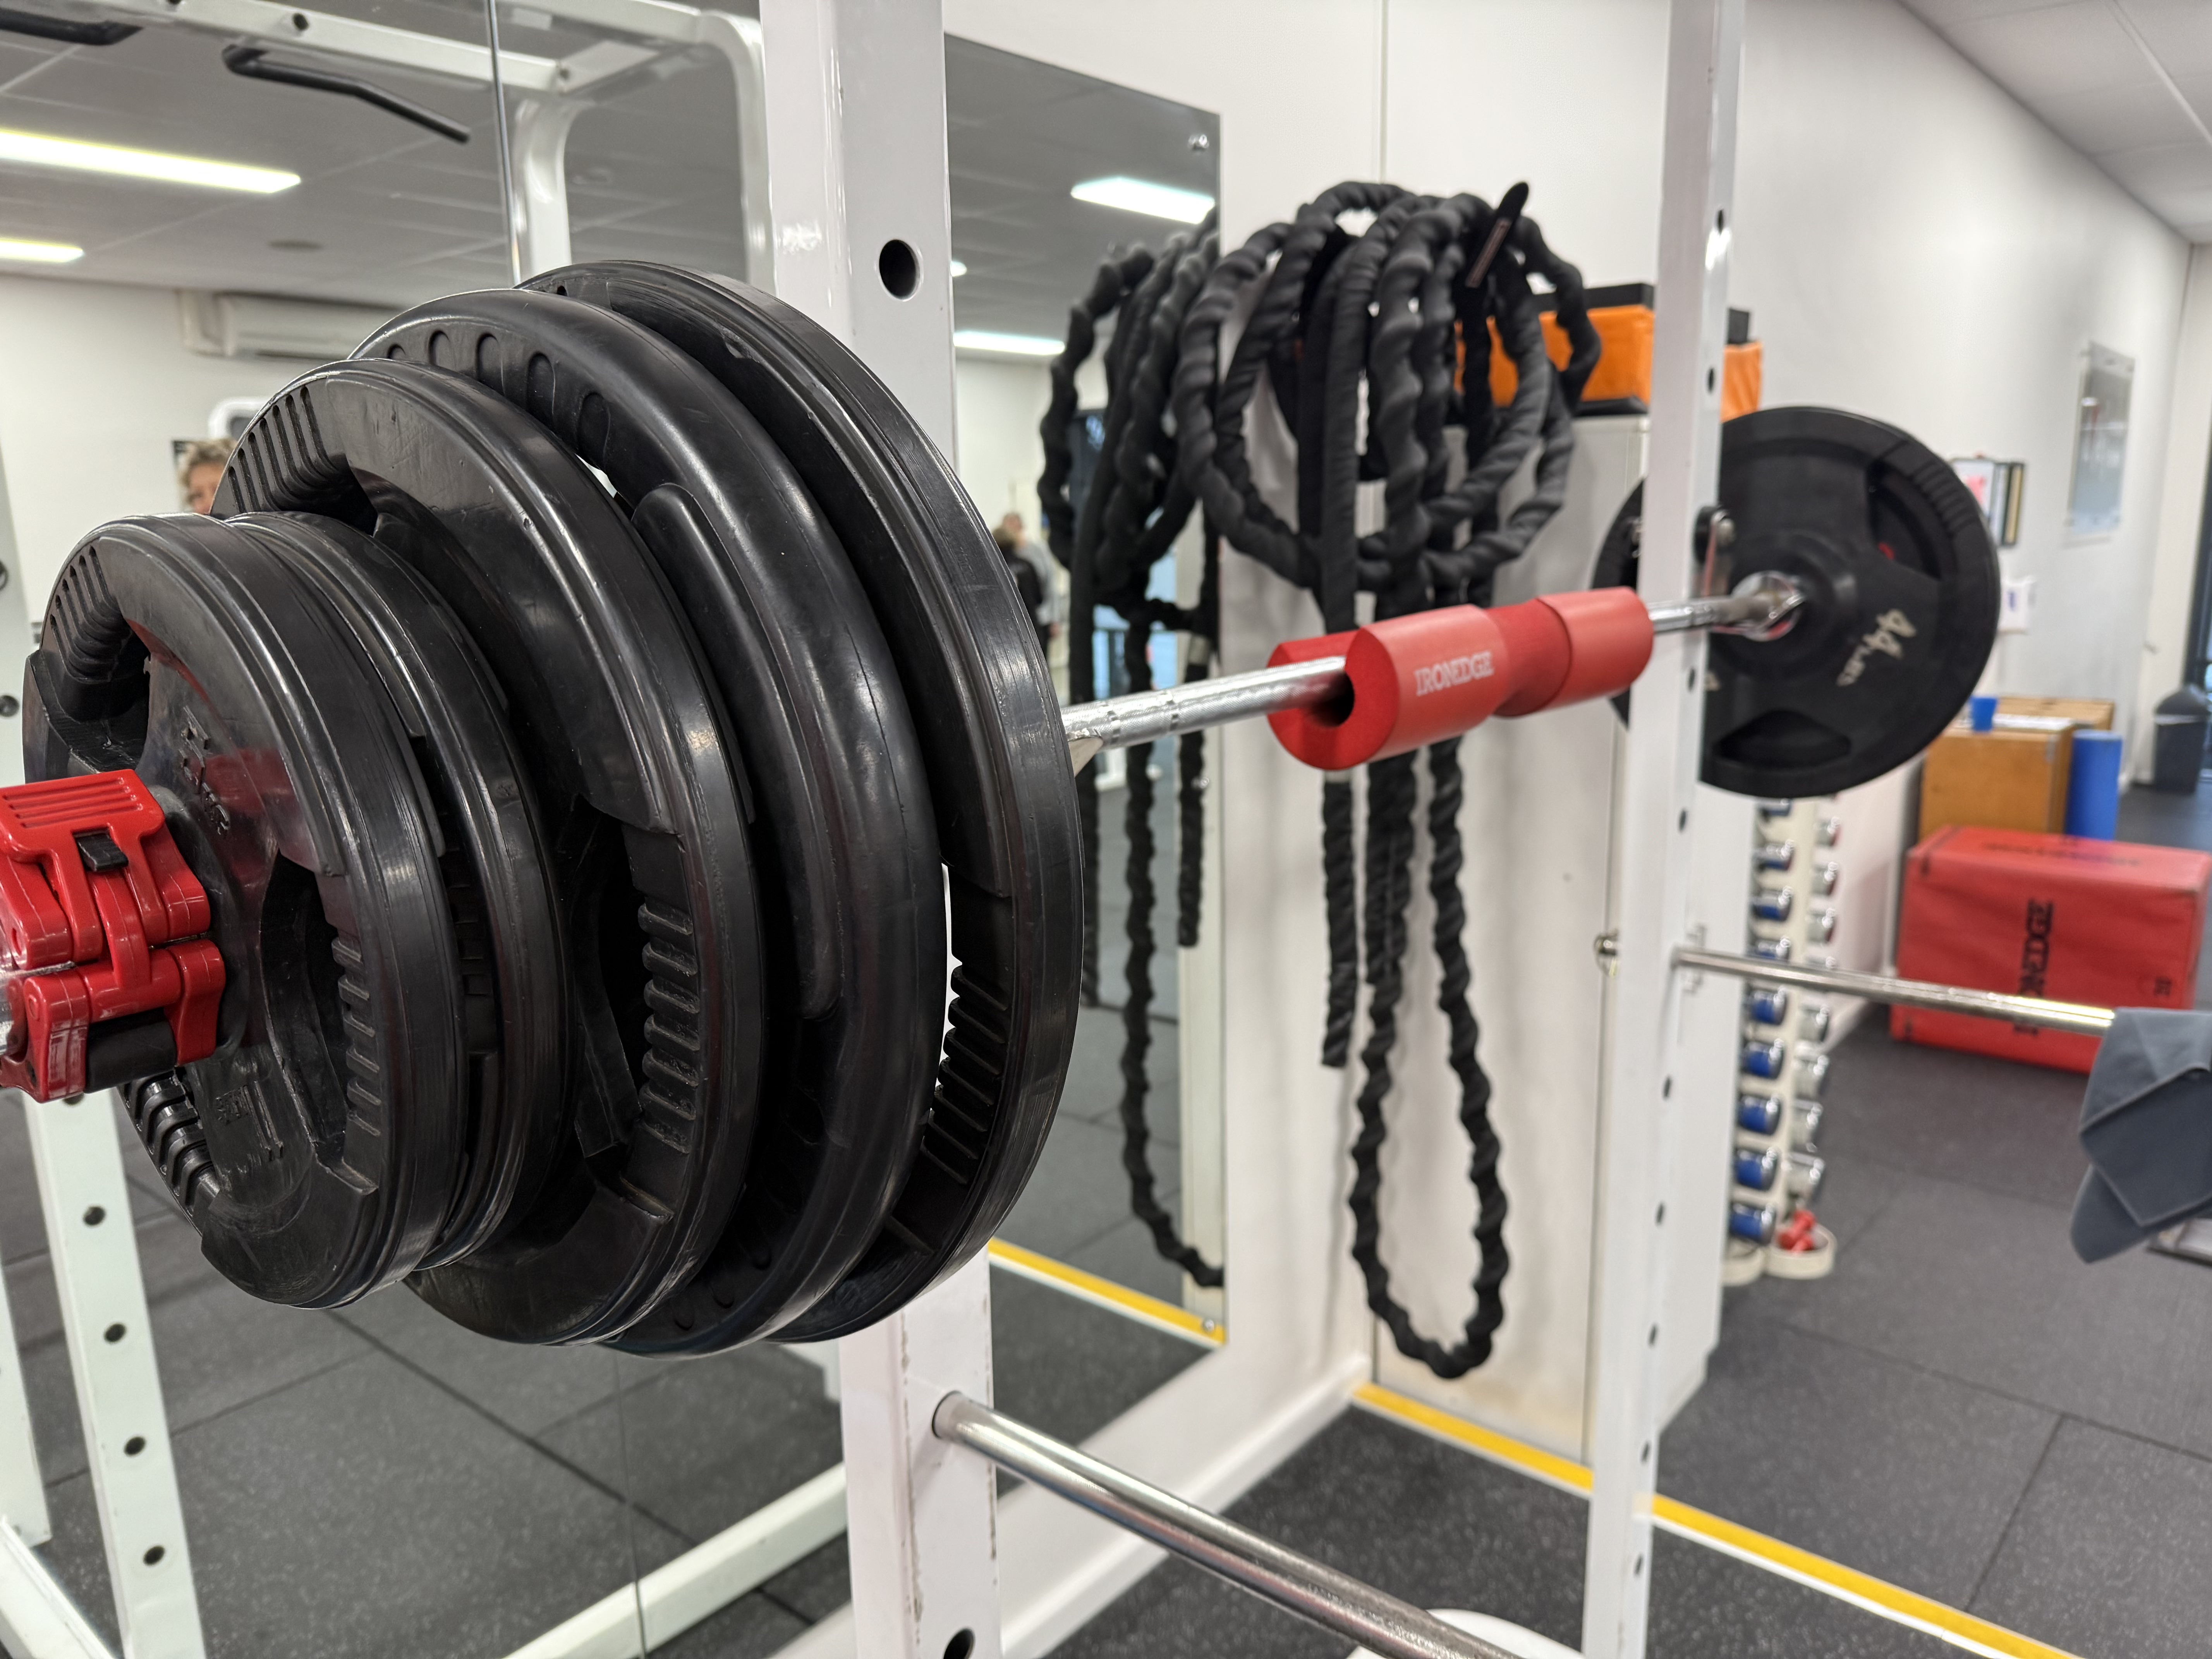
If you’ve ever spent time in a gym, you’ve probably seen people (or been one of them) lifting weights. There are many reasons why humans lift weights in gyms, most of which stem from the fact that modern life has removed many of the weight-bearing activities that we used to undertake and weight lifting can build muscle and strength, both of which are often useful.
The picture for today’s post is of some weights, roughly 140kg, arranged for a human to lift them. But, let’s be honest, this is probably the least efficient and dumbest way to lift this much weight. Even the smallest electric forklift can easily lift this much weight, probably up to ten times this, so why is someone in a gym wasting time with this pointless task? The answer, of course, is that the goal of this activity is not to ensure that these weights are lifted. The goal of weight training is to build technique, muscle, and stamina in the individual and the lifting of these weights is the mechanism that we use to achieve this.
Very few people could start with a very heavy weight and just swing it around – in fact, many people would hurt themselves if they did so, because their body has not been trained or developed to do it. Weight training takes practice, seeking steady improvement, utilising well-crafted sessions of activity, controlled addition of weight, and the careful use of rest periods, to ensure that muscles are growing as we want and that we’re not overstraining the body. Weight training is an ergodic activity, it takes effort over time to get better at it. Yes, I could go and get the forklift, but that wouldn’t actually help me as a person to build up the things that weight training should improve.
I regret that I can’t remember where I first saw weight lifting used as an analogy for learning, or I’d credit the person, but I’m definitely not claiming it as mine – I just like it. I keep circling back to this as because learning is also an ergodic activity. At school and university, we assign tasks to students that have some sort of outcome but we are very rarely really interested in the outcome itself, we care about the application of effort over time into the process that will create the outcome – just like weightlifting. The point is not for the student to give us a computer program (say), the point is for the student to apply their knowledge and skill to interpret what we want and then take the time and effort to go through the process of building the computer program. That way, they start to get “stronger” at writing computer programs and, if we design things well in the learning environment, we hope that they will keep building those coding muscles until they can reach a professional level of competency (or at least the entry level to that).
This is one of the problems with students offloading their coding to a prompt-driven Generative AI approach- they’ve brought in a forklift to lift the weight. I mean, yes, the weight has technically been lifted but that’s not the point of the exercise. We’re already seeing evidence that it’s very hard to transfer useful knowledge from prompt-driven approaches, where students do amazingly well in the exercises and then utterly tank the exam because they never actually knew how to do something.
I won’t bore you all with my usual mutterings about how cognitive load theory explains all of this, and is not a bad approximation to weight training in many ways, but none of the shortcomings in GenAI-“assisted” learning are much surprise when you think about whether any real effort is going into the activity and if it’s actually a way of learning that we can make good use of.
Some people will only ever need the forklift and that’s not a problem; why go to all the trouble, if you don’t actually want to develop that part of yourself and don’t need to? But, for those who really wanted to develop the capability? Maybe leave the forklift until you’ve trained yourself first.
The Simplest Test of LLMs for Research
Posted: August 9, 2026 Filed under: Education, Opinion | Tags: advocacy, AI, artificial intelligence, chatgpt, education, higher education, reflection, teaching approaches, technology, thinking, writing 1 CommentI am teaching a general research preparation course for Masters students across my (shiny new) University called RESE 5000 Foundations of Research. It’s a four week course as part of a much larger sequence and covers research design, alternatives in research design, paradigms, quant/qual, and a lot of hands on work to develop a small but focussed research design glossary for these students. The useful part of this is that they have got more vocabulary and more knowledge with which to discuss things, especially with their supervisors. It’s all colleges and disciplines so it’s a pretty broad course in coverage.
The Activity
Because they have to go and find appropriate references for methods and approaches in their own discipline, we bootstrap with literature reviews: how do you find the papers and published works that support your research? I conduct a very simple exercise in the first workshop:
- Open up a Google Scholar page and search for a term I give them. (It’s often mastery learning.)
- Then we discuss as a class what we found as the top 10. It’s almost always exactly the same and, because inside the Uni we’re subscribed to all of the various pub venues, you can click on all of them and open them up.
- Then I ask them to open up ChatGPT (or “LLM of choice” if they have a strong preference) and ask it for top ten references for the same search term.
- And then we compare.
- And then we check to see how many are duplicates.
- And then we check to see how many don’t actually exist.
I did this on Thursday last week for the subject of mastery learning (told you), and of the ten references I got back, 2 and 3 were effectively the same, 10 didn’t exist, and two others kind of matched. But, more importantly, everyone got something different. We had gone from “this is what you get when you search” to “here’s something that might be right and it will change every time”. By my estimate, students who start with the LLM based approach need to spend up to twice as much time checking to make sure it’s not wrong. I think that’s inefficient.
The Rationale
I don’t use generative AI at all in my work, unless for specific research or illustrative purposes, although I am starting to work with Apertus, the Swiss-based model that meets EU training standards, is offset for power, and cooled by the waters of Lake Lugano. As a journal associate editor and regular reviewer, however, I am being driven to distraction by the sheer number of fabricated references I’m encountering. I have a very simple rule on this – you cannot build good research on bad research and evidence of reference fabrication is evidence of a flawed process.
I tell the students that how they use Generative AI is up to them, their supervisors, and whoever employs them, but I also tell them that good research is supported by solid citations. If I can’t run a simple demo in class and get right answers more than 90% of the time, this tool is not fit for purpose.
Oh, but you could craft the prompt/use agents
Yeah, I could. I’ve had students do that, where they change the prompt to only provide actual works that can be looked up. The first problem is that you still sometimes get dud references, the second is that this is most likely using some form of agentic checking layer over the top of the stochastic generation. Now, I am not a young CS person, and I cut my teeth coding for 16K, 32K, 640K memory spaces, which means that the aesthetics I value in code include efficiency and minimalism. With much of CS being searching and sorting, I find it more than vaguely irritating that the solution to “the machine is making things up” is not “stop using the machine” but “check what it made up to see if it worked and then throw the dice again until you get it right.”
Searching is not just about finding what is there, it is also about knowing what is not there and clearly indicating that. We used to value precision and recall, and I am seeing far too many false positives to make me confident that this is still being taken seriously. The speed with which a synthetic answer is generated when no answer truly exists worries me, because most people don’t check as much as I do.
The dull conclusion
There are things that AI is good at. There are things that Generative AI is good at. But given how easy it is for me to show students what it’s not good at, I’m going to keep recommending that they avoid it for reference generation for the foreseeable future.
Work and Life
Posted: January 21, 2026 Filed under: Opinion | Tags: community, higher education, personal development, reflection, social media, teaching 1 Comment
I’ve just returned from a brief holiday on the Australian East Coast and I had a chance to think about what the new leadership role at the Uni will mean. One thing I felt I had to do, although it was honestly a tough decision to make, was tidy up the work/personal aspects of my social media. This means unfriending (what a loaded term) some people who I’ve known through work for a while. It wasn’t easy to do and I’m still thinking about it. Why did I do it?
I will have new staff who don’t really know me, in a school where half of the team also don’t really know each other that well, and we are bringing together two successful, fully-formed, and slightly different academic cultures. Bringing these groups together, meeting their needs, being focused, being present, listening… all of these things are essential and they need the best of my professional aspects. I have recently found out that I have not been listening as well as I should and that’s on me to fix, to be the person I always wanted to be and claim that I am but, obviously, sometimes fall short at. (The irony is that I consider it likely that people have given me clear indications that I haven’t been seeming to listen enough to care about their input – but I haven’t noticed. Ick. I’m striving to pay attention now.)
I need to be “work Nick” primarily, because those are the skills, the focus, and the type of presence that they need. I have many interests but bringing them into the work space is not always the best use of anyone’s time and it’s certainly not what a junior teaching team academic needs when I’m managing them. To make the dividing line really clear, both for my ease of processing and for consistency, I’ve removed a number of people from my Facebook friends who are primarily work people, so that I don’t have some weird two speed situation of “I friended this person but this other one.” I’ve also had to unfriend someone from my own town who I’ve known for years but now we have a potential conflict because of our roles. I’ve had to do this before when I realised that you couldn’t friend some students and not others, even though there may have been an existing RW connection because my home town has about 1.5 degrees of separation.
(Years ago, there was even a student group “Nick Falkner won’t friend me on Facebook” and the student laser printer was part of it. No, I never added the laser printer.)
I’m unsure if removing work people was the right decision or not, as it means I can’t see what people who I met through work, and I like, are up to – but I’ve taken this decision as a good way to make it easier for me to set things up well for my new role and do the right thing by the people I’m managing. A part of me hopes that, after a year or two, when the culture is established and I’ve got to know people better, I can go back and reconnect to the other people, if they’ll have me.
I’d be really interested to know what people think and how you handle the work/personal social separation! Feel free to tell me how wrong or right you think I got it.
First day at the new (old) job
Posted: January 5, 2026 Filed under: Education | Tags: AI, education, higher education, learning, reflection, teaching, writing Leave a commentI sit at the desk in my new office on Level 5 of the building I’ve been working in for over 10 years, as part of a different university and with a new job title. The foundation universities of the University of Adelaide and the University of South Australia are now officially merged as Adelaide University, which is now roughly the 5th largest University in Australia. I am no longer the Deputy Head of the School of Computer and Mathematical Sciences, as neither the position nor that school still exist! I am an Academic Lead in the School of Computer Science and Information Technology, with responsibilities around educational research and our education specialist staff, and now have roughly 15 staff to manage as part of our new model.
Last year was pretty successful in many ways, the ITiCSE WG delivered an amazing report with some fantastic resources, I was part of a successful grant, the CompEd WG made fantastic progress (still going into the new year as we tidy that up), and I felt like, for the first time in ages, I really had the opportunity to look into research into detail. But it was very tiring, being the last year of a long push that started during the pandemic and finishing in a year where I got so sick that my hair started falling out and my overall physical health took a 10% hit. Much better now, although my hair is still my hair! And now the universities are merged and I’m part of the brand new Adelaide University. It’s a great time to look forward and set some themes for this year. But let’s do a 50,000 foot flyover of my job.
Research: From a research perspective, the CARD WG outcome has reinforced how important it is to have learning resources and tools that lead to the outcomes that you want – this is especially true in the face of the rise of Generative AI, where it is terrifyingly easy to sidestep any cognitive or memory work totally in the production of artefacts. For years, we got away with requiring student to produce something as evidence of a process of production, which entailed cognition, learning, and application of effort over time. Artefacts like the CARD Research Cards can’t be completed with generative AI, people have to interact with them. There are opportunities to engage with something, consider it, respond to it, and develop your skills accordingly. I sketched out some ideas last year about a working group based on tools and approaches for learning that specifically could not be carried out with Generative AI, but haven’t done anything with them. I most likely can’t do any WGs this year for timing and commitment reasons but I might pitch something next year about all the ways that game-based approaches to learning and non-AI-based scalable aspects of personalised learning can be useful in the era of Generative AI. The random and reflexive aspects of the cards make the process inherently focused on the individual – but I’ll return to this thought later. More stuff needs to happen with CARD but that’s a next week thought.
Teaching: I’m teaching a couple of courses this year, mostly around the postgraduate level, working on research skill development and computational research methods. This will be the first curricular application of the CARD system, realised as both physical cards and an online version developed by our fantastic media team in the learning design space. It will be great to be back in the classroom more!
Leadership and Service: I have 15 direct reports and will be getting to know them over the next few weeks. I suspect I’ll be in three places in a given week, my old stomping ground next to the Art Gallery on North Terrace, City West campus, and Mawson Lakes Campus. Learning what they need, and how I can use my experience and knowledge to help them, is one of my highest priorities prior to the start of Semester 1. I have had an unconventional pathway to academia but I still have many lenses of privilege to acknowledge and work through when I work with anybody else. There will be a lot of listening and thinking on my part. I have a number of duties for various SIGCSE roles that I’m looking forward to getting back into now that I’m finally healthy again.
Travel: I’ve been travelling a lot and the plane trips have been frequent, long, and not the best thing for me in any sense. I’m planning to spend about three months in Finland this year as part of a visiting fellowship at University of Jyväskylä but this will involve less flying and more time concentrated in one place. I hope that this will allow me to do better work and be more present…
Speaking of presence, I think that’s my most important theme for this year: present in my personal life, present for my students, present for my research collaborators, and definitely present for my colleagues, especially those who I’m managing. Something has been showing up in my shape at various points of the year but I’m not sure how much of it has been me. Let’s see what I can do this year.
Happy new year, everyone!
2025 ACM Global Computing Education Conference in Botswana, 21-22 October – Another Working Group!
Posted: May 8, 2025 Filed under: Education | Tags: botswana, community, comped, education, higher education, research, working groups Leave a commentWell, well, a third post in the year? Who made me research active? (I have not yet really been made research rigorous, despite some valiant attempts) I’m very excited to announce that we’ve got a working group advertised for the 2025 ACM Global Computing Education Conference in Botswana and we’d love to get more people involved. The Main conference runs Oct 23-25, Working Groups Oct 21-22 and Doctoral Consortium Oct 22.
You can join A/Prof Claudia Szabo, me, Dr. Munienge Mbodila, and Prof Judy Sheard as we work to assess impact, analyse the effects on higher ed institutions, and identify the challenges, with a focus on the Global South.
Brief motivation
This ACM working group, fitting within the broader remit of an ACM Task Force, aims to investigate the ethical and societal impacts of Generative AI tools within the higher computing education landscape within the Global South and to provide guidelines for the ethical incorporation of AI into teaching and assessment in CS1, CS2 and CS3, considering the desired learning outcomes at each level, student learning behaviour, validity of assessment and academic integrity, and local ethical frameworks. This working group will conduct a landscape analysis on Global South ethical questions related to the use of Generative AI tools in higher education contexts, identifying promising principles, challenges, and ways to navigate the implementation of Generative AI in ethical and principled ways. This working group builds on the ITiCSE working group with a similar name, and is developed under the guidance of two of that working group’s leaders, namely Alison Clear and Tony Clear. It focuses the lens on the Global South and specifically on CS1-3 perspectives within this space.
Get Involved!
If you want to read more or apply, please follow the link to the WG page and fill out your application before the end of May 9, anywhere around the world! There are excellent travel grants available to support this so check those out, too!
ITiCSE 2025: Working Group 1 – exciting news!
Posted: February 14, 2025 Filed under: Education | Tags: computer science education research, education, games, higher education, ITiCSE, learning, play, research, teaching, technology, thinking Leave a commentTwo posts in the same year? Something must be up… and it is! After the successful presentation of Dr Rebecca Vivian and my work at Koli as both DC tool and award winning poster/demo, I looked into taking this to a working group and Dr Miranda Parker agreed to co-lead it with me, as Rebecca is currently on leave. Miranda and I have been digging into all of the aspects of this in the middle of both our day jobs and it’s been a lot of fun to work on! You think you’ve got difficult collaborators? Miranda has to listen to me pontificate about ontologies, paradigms, and philosophies!
It’s really important to recognise Rebecca’s ongoing connection with this project, as it’s still very much Rebecca’s work that got us here and she will continue to be a significant part of this, we’re just making sure we have the co-leadership of people who aren’t on leave to make it work. It’s really exciting that our Workgroup has gone to the advertisement stage!
You can see all of the WG proposals here, and sign up (maybe to ours if you like what you read here) here. We’re happy to answer questions and it’s going to be an amazing combination of serious play, serious research, and great fun.
Here’s the ad as a cut and paste!
WG1 – Paradigms, Methods, and Outcomes, Oh My!: Refining and Evolving a Research Knowledge Development Activity for Computer Science Education
Leaders:
- Nick Falkner, nickolas.falkner@adelaide.edu.au
- Miranda Parker, miranda.parker@uncc.edu
Motivation:
Computer Science Education Research (CSER) combines the frequently quantitative approaches of computer science, engineering, and mathematics with the often more qualitative techniques seen in psychology, sociology, behavioural science, and education. It can be challenging to select appropriate research methods in effective and efficient ways.
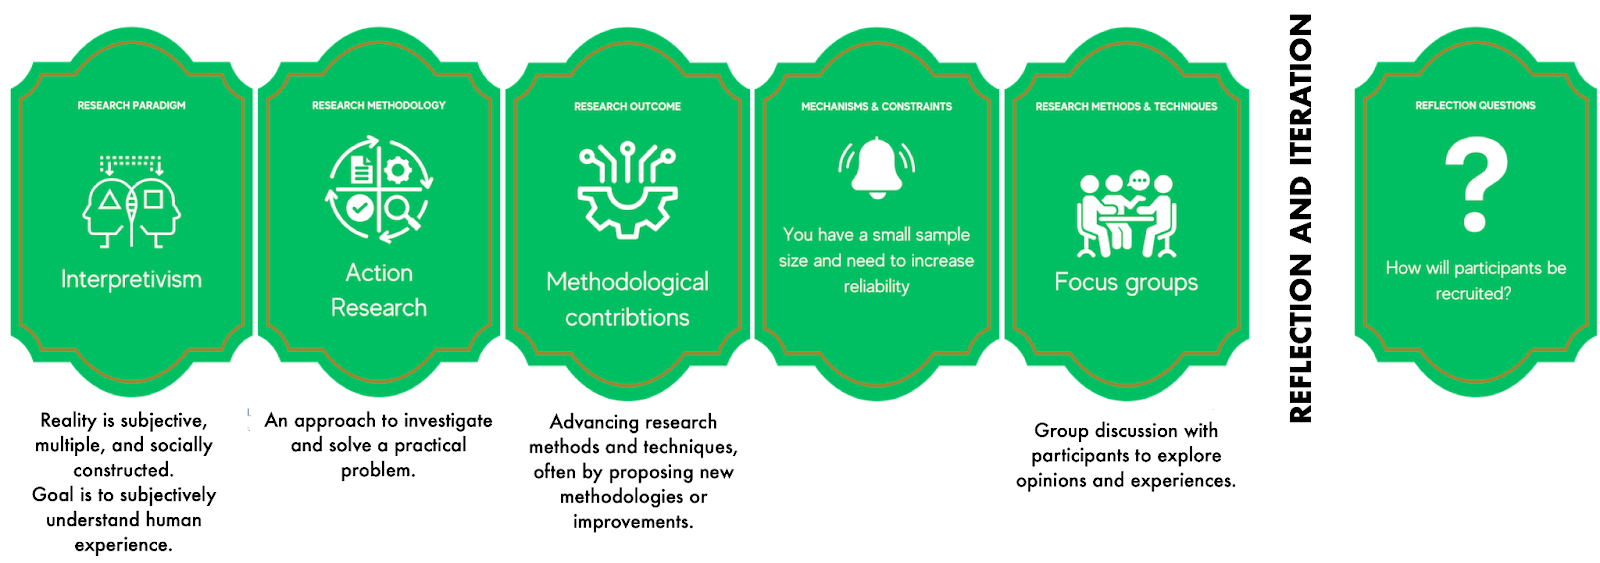
Inspired by the use of card-based techniques in the classroom, the Research Alternatives Exercise (RAE) is a pack of 105 cards introducing a wide range of possible research approaches. RAE provides alternatives to a participant’s current research plans using new random lenses, leading to the sketch of a new research design. The participant refers to their own design through the lens of the randomly drawn card, working to see how well this fits, informs, or improves what they have done.
The initial version of the card deck and examples of play won best paper/demo at Koli Calling 2024 and an example “run” is shown below:
Goals:
- review and modify the existing deck through collaboration in the WG
- develop a version of the deck that can be shared and used widely across the CSER community,
- develop a concise support glossary for the cards
Methodology:
The current deck will be shared with participants, to support targeted literature review, research, and consultation to:
- refine the terminology used for categories, which are currently paradigms, methodologies, outcomes, and methods,
- refine the components within categories,
- review the existing rules for suitability,
- develop the first draft of the support glossary, and
- develop different decks and play approaches for specific purposes.
Following kickoff at the end of March, we will work on Items 1 and 3, aiming for completion by the start of May. When categories are finalized, we will undertake Item 2, where each group member will work in small groups to review each category. Findings will be presented to the whole group by the beginning of June, for further discussion and collaboration. Each sub-group will be responsible for the glossary elements of their contribution, to be completed and reviewed for the start of the in-person WG time. Each working group member will be asked to share the deck with colleagues to provide feedback.
Member Selection:
We seek at least 8-10 individuals to share the required work manageably.
We are looking for participants with at least one of:
- Experience with a wide variety of research methodologies,
- Experience in supervising graduate students,
- Interest and knowledge in using game-based and facilitated techniques, or
- Experience with research skills development.
We actively invite applications from disciplines beyond computing for diversity in research skills development experience. We seek a diversity of experience, background, and culture, to ensure that the feedback encompasses the full range of CSER community experience. We also welcome student applications.
Successful applicants will:
- Attend fortnightly 60-90 minute online progress meetings, held from mid-late March to the end of June,
- Register for ITiCSE 2025,
- Physically attend the full duration of the working group, and
- Make significant contributions during the pre- and post-ITiCSE Working Group activities (3-4 hours a week).


